
后续步骤
最后更新于 2026-11-07 | 编辑此页
概述
问题
- 什么是
SummarizedExperiment? - 什么是 Bioconductor?
学习目标
- 介绍 Bioconductor 项目。
- 介绍数据容器的概念。
- 概述在组学分析中广泛使用的
SummarizedExperiment。
后续步骤
生物信息学中的数据通常较为复杂。为了应对这一问题,开发者定义了专门的数据容器(称为类),以匹配他们需要处理的数据属性。
这一方面是 Bioconductor1 项目的核心,该项目在各个包中使用相同的 核心数据基础设施。这无疑促成了 Bioconductor 的成功。Bioconductor 包开发者建议利用现有基础设施,以确保整个项目的一致性、互操作性和稳定性。
为了演示这类组学数据容器,我们将介绍
SummarizedExperiment 类。
SummarizedExperiment
下图展示了 SummarizedExperiment 类的结构。

SummarizedExperiment 类的对象包含:
一个(或多个)测定,包含定量组学数据(表达数据),以矩阵类对象形式存储。特征(基因、转录本、蛋白质……)沿行定义,样本沿列定义。
一个包含样本协变量的 样本元数据 槽,以数据框形式存储。该表的行代表样本(行与表达数据的列完全匹配)。
一个包含特征协变量的特征元数据槽,以数据框形式存储。该数据框的行与表达数据的行完全一致。
SummarizedExperiment
的协调特性保证了在数据处理过程中,不同槽的维度始终保持一致(即表达数据中的列与样本元数据中的行,以及表达数据中的行与特征元数据中的行)。例如,如果我们需要从测定中剔除一个样本,该样本将在同一操作中自动从样本元数据中移除。
元数据槽可以增加额外的协变量(列),而不会影响其他结构。
创建 SummarizedExperiment
为了创建 SummarizedExperiment,我们将从 CSV
文件中创建各个组成部分,即计数矩阵、样本和基因元数据。这通常是 RNA-Seq
数据的提供方式(在原始数据经过处理之后)。
-
表达矩阵:我们加载计数矩阵,并指定第一列包含行/基因名称,然后将
data.frame转换为matrix。您可以点击此链接下载。
R
count_matrix <- read.csv("data/count_matrix.csv",
                         row.names = 1) |>
    as.matrix()

count_matrix[1:5, ]
输出
        GSM2545336 GSM2545337 GSM2545338 GSM2545339 GSM2545340 GSM2545341
Asl           1170        361        400        586        626        988
Apod         36194      10347       9173      10620      13021      29594
Cyp2d22       4060       1616       1603       1901       2171       3349
Klk6           287        629        641        578        448        195
Fcrls           85        233        244        237        180         38
        GSM2545342 GSM2545343 GSM2545344 GSM2545345 GSM2545346 GSM2545347
Asl            836        535        586        597        938       1035
Apod         24959      13668      13230      15868      27769      34301
Cyp2d22       3122       2008       2254       2277       2985       3452
Klk6           186       1101        537        567        327        233
Fcrls           68        375        199        177         89         67
        GSM2545348 GSM2545349 GSM2545350 GSM2545351 GSM2545352 GSM2545353
Asl            494        481        666        937        803        541
Apod         11258      11812      15816      29242      20415      13682
Cyp2d22       1883       2014       2417       3678       2920       2216
Klk6           742        881        828        250        798        710
Fcrls          300        233        231         81        303        285
        GSM2545354 GSM2545362 GSM2545363 GSM2545380
Asl            473        748        576       1192
Apod         11088      15916      11166      38148
Cyp2d22       1821       2842       2011       4019
Klk6           894        501        598        259
Fcrls          248        179        184         68
R
dim(count_matrix)
输出
[1] 1474 22- 描述样本的表格,可在此链接获取。
R
sample_metadata <- read.csv("data/sample_metadata.csv")
sample_metadata
输出
       sample     organism age    sex   infection  strain time     tissue mouse
1  GSM2545336 Mus musculus   8 Female  InfluenzaA C57BL/6    8 Cerebellum    14
2  GSM2545337 Mus musculus   8 Female NonInfected C57BL/6    0 Cerebellum     9
3  GSM2545338 Mus musculus   8 Female NonInfected C57BL/6    0 Cerebellum    10
4  GSM2545339 Mus musculus   8 Female  InfluenzaA C57BL/6    4 Cerebellum    15
5  GSM2545340 Mus musculus   8   Male  InfluenzaA C57BL/6    4 Cerebellum    18
6  GSM2545341 Mus musculus   8   Male  InfluenzaA C57BL/6    8 Cerebellum     6
7  GSM2545342 Mus musculus   8 Female  InfluenzaA C57BL/6    8 Cerebellum     5
8  GSM2545343 Mus musculus   8   Male NonInfected C57BL/6    0 Cerebellum    11
9  GSM2545344 Mus musculus   8 Female  InfluenzaA C57BL/6    4 Cerebellum    22
10 GSM2545345 Mus musculus   8   Male  InfluenzaA C57BL/6    4 Cerebellum    13
11 GSM2545346 Mus musculus   8   Male  InfluenzaA C57BL/6    8 Cerebellum    23
12 GSM2545347 Mus musculus   8   Male  InfluenzaA C57BL/6    8 Cerebellum    24
13 GSM2545348 Mus musculus   8 Female NonInfected C57BL/6    0 Cerebellum     8
14 GSM2545349 Mus musculus   8   Male NonInfected C57BL/6    0 Cerebellum     7
15 GSM2545350 Mus musculus   8   Male  InfluenzaA C57BL/6    4 Cerebellum     1
16 GSM2545351 Mus musculus   8 Female  InfluenzaA C57BL/6    8 Cerebellum    16
17 GSM2545352 Mus musculus   8 Female  InfluenzaA C57BL/6    4 Cerebellum    21
18 GSM2545353 Mus musculus   8 Female NonInfected C57BL/6    0 Cerebellum     4
19 GSM2545354 Mus musculus   8   Male NonInfected C57BL/6    0 Cerebellum     2
20 GSM2545362 Mus musculus   8 Female  InfluenzaA C57BL/6    4 Cerebellum    20
21 GSM2545363 Mus musculus   8   Male  InfluenzaA C57BL/6    4 Cerebellum    12
22 GSM2545380 Mus musculus   8 Female  InfluenzaA C57BL/6    8 Cerebellum    19
R
dim(sample_metadata)
输出
[1] 22 9- 描述基因的表格,可在此链接获取。
R
gene_metadata <- read.csv("data/gene_metadata.csv")
gene_metadata[1:10, 1:4]
输出
      gene ENTREZID
1      Asl   109900
2     Apod    11815
3  Cyp2d22    56448
4     Klk6    19144
5    Fcrls    80891
6   Slc2a4    20528
7     Exd2    97827
8     Gjc2   118454
9     Plp1    18823
10    Gnb4    14696
                                                                         product
1                                 argininosuccinate lyase, transcript variant X1
2                                         apolipoprotein D, transcript variant 3
3   cytochrome P450, family 2, subfamily d, polypeptide 22, transcript variant 2
4                           kallikrein related-peptidase 6, transcript variant 2
5                  Fc receptor-like S, scavenger receptor, transcript variant X1
6            solute carrier family 2 (facilitated glucose transporter), member 4
7                                          exonuclease 3'-5' domain containing 2
8                            gap junction protein, gamma 2, transcript variant 1
9                           proteolipid protein (myelin) 1, transcript variant 1
10 guanine nucleotide binding protein (G protein), beta 4, transcript variant X2
      ensembl_gene_id
1  ENSMUSG00000025533
2  ENSMUSG00000022548
3  ENSMUSG00000061740
4  ENSMUSG00000050063
5  ENSMUSG00000015852
6  ENSMUSG00000018566
7  ENSMUSG00000032705
8  ENSMUSG00000043448
9  ENSMUSG00000031425
10 ENSMUSG00000027669
R
dim(gene_metadata)
输出
[1] 1474 9我们将根据这些表格创建一个 SummarizedExperiment:
将用作
assay的计数矩阵描述样本的表将用作 样本元数据 槽
描述基因的表将用作 特征元数据 槽
为此,我们可以使用 SummarizedExperiment
构造函数将不同的部分组合在一起:
R
## BiocManager::install("SummarizedExperiment")
library("SummarizedExperiment")
首先,我们确保计数矩阵和样本注释中的样本顺序一致,且计数矩阵和基因注释中的基因顺序也一致。
R
stopifnot(rownames(count_matrix) == gene_metadata$gene)
stopifnot(colnames(count_matrix) == sample_metadata$sample)
R
se <- SummarizedExperiment(assays = list(counts = count_matrix),
                           colData = sample_metadata,
                           rowData = gene_metadata)
se
输出
class: SummarizedExperiment
dim: 1474 22
metadata(0):
assays(1): counts
rownames(1474): Asl Apod ... Lmx1a Pbx1
rowData names(9): gene ENTREZID ... phenotype_description
  hsapiens_homolog_associated_gene_name
colnames(22): GSM2545336 GSM2545337 ... GSM2545363 GSM2545380
colData names(9): sample organism ... tissue mouse
保存数据
将数据导出到电子表格(如我们在之前的章节中所做的那样)存在若干局限性,例如第一章中所述的问题(小数点分隔符可能与
, 和 .
不一致,且缺乏变量类型定义)。此外,将数据导出到电子表格仅适用于数据框和矩阵等矩形数据。
一种更通用的数据保存方式是使用 saveRDS
函数,该方法专用于
R,且保证在任何操作系统上均能正常运行。这样保存对象将在磁盘上生成二进制表示(此处使用
rds 文件扩展名),随后可以使用 readRDS
函数将其重新加载到 R 中。
R
saveRDS(se, file = "data_output/se.rds")
rm(se)
se <- readRDS("data_output/se.rds")
head(se)
总之,对于需要在 R 中保存并再次加载的数据,使用 saveRDS
和 readRDS 进行保存和加载是首选方法。如果需要与不使用 R
的人员共享表格数据,则导出为基于文本的电子表格是一个不错的替代方案。
利用这种数据结构,我们可以使用 assay
函数访问表达矩阵:
R
head(assay(se))
输出
        GSM2545336 GSM2545337 GSM2545338 GSM2545339 GSM2545340 GSM2545341
Asl           1170        361        400        586        626        988
Apod         36194      10347       9173      10620      13021      29594
Cyp2d22       4060       1616       1603       1901       2171       3349
Klk6           287        629        641        578        448        195
Fcrls           85        233        244        237        180         38
Slc2a4         782        231        248        265        313        786
        GSM2545342 GSM2545343 GSM2545344 GSM2545345 GSM2545346 GSM2545347
Asl            836        535        586        597        938       1035
Apod         24959      13668      13230      15868      27769      34301
Cyp2d22       3122       2008       2254       2277       2985       3452
Klk6           186       1101        537        567        327        233
Fcrls           68        375        199        177         89         67
Slc2a4         528        249        266        357        654        693
        GSM2545348 GSM2545349 GSM2545350 GSM2545351 GSM2545352 GSM2545353
Asl            494        481        666        937        803        541
Apod         11258      11812      15816      29242      20415      13682
Cyp2d22       1883       2014       2417       3678       2920       2216
Klk6           742        881        828        250        798        710
Fcrls          300        233        231         81        303        285
Slc2a4         271        304        349        715        513        320
        GSM2545354 GSM2545362 GSM2545363 GSM2545380
Asl            473        748        576       1192
Apod         11088      15916      11166      38148
Cyp2d22       1821       2842       2011       4019
Klk6           894        501        598        259
Fcrls          248        179        184         68
Slc2a4         248        350        317        796
R
dim(assay(se))
输出
[1] 1474 22我们可以使用 colData 函数访问样本元数据:
R
colData(se)
输出
DataFrame with 22 rows and 9 columns
                sample     organism       age         sex   infection
           <character>  <character> <integer> <character> <character>
GSM2545336  GSM2545336 Mus musculus         8      Female  InfluenzaA
GSM2545337  GSM2545337 Mus musculus         8      Female NonInfected
GSM2545338  GSM2545338 Mus musculus         8      Female NonInfected
GSM2545339  GSM2545339 Mus musculus         8      Female  InfluenzaA
GSM2545340  GSM2545340 Mus musculus         8        Male  InfluenzaA
...                ...          ...       ...         ...         ...
GSM2545353  GSM2545353 Mus musculus         8      Female NonInfected
GSM2545354  GSM2545354 Mus musculus         8        Male NonInfected
GSM2545362  GSM2545362 Mus musculus         8      Female  InfluenzaA
GSM2545363  GSM2545363 Mus musculus         8        Male  InfluenzaA
GSM2545380  GSM2545380 Mus musculus         8      Female  InfluenzaA
                strain      time      tissue     mouse
           <character> <integer> <character> <integer>
GSM2545336     C57BL/6         8  Cerebellum        14
GSM2545337     C57BL/6         0  Cerebellum         9
GSM2545338     C57BL/6         0  Cerebellum        10
GSM2545339     C57BL/6         4  Cerebellum        15
GSM2545340     C57BL/6         4  Cerebellum        18
...                ...       ...         ...       ...
GSM2545353     C57BL/6         0  Cerebellum         4
GSM2545354     C57BL/6         0  Cerebellum         2
GSM2545362     C57BL/6         4  Cerebellum        20
GSM2545363     C57BL/6         4  Cerebellum        12
GSM2545380     C57BL/6         8  Cerebellum        19
R
dim(colData(se))
输出
[1] 22 9我们还可以使用 rowData 函数访问特征元数据:
R
head(rowData(se))
输出
DataFrame with 6 rows and 9 columns
               gene  ENTREZID                product    ensembl_gene_id
        <character> <integer>            <character>        <character>
Asl             Asl    109900 argininosuccinate ly.. ENSMUSG00000025533
Apod           Apod     11815 apolipoprotein D, tr.. ENSMUSG00000022548
Cyp2d22     Cyp2d22     56448 cytochrome P450, fam.. ENSMUSG00000061740
Klk6           Klk6     19144 kallikrein related-p.. ENSMUSG00000050063
Fcrls         Fcrls     80891 Fc receptor-like S, .. ENSMUSG00000015852
Slc2a4       Slc2a4     20528 solute carrier famil.. ENSMUSG00000018566
        external_synonym chromosome_name   gene_biotype  phenotype_description
             <character>     <character>    <character>            <character>
Asl        2510006M18Rik               5 protein_coding abnormal circulating..
Apod                  NA              16 protein_coding abnormal lipid homeo..
Cyp2d22             2D22              15 protein_coding abnormal skin morpho..
Klk6                Bssp               7 protein_coding abnormal cytokine le..
Fcrls      2810439C17Rik               3 protein_coding decreased CD8-positi..
Slc2a4            Glut-4              11 protein_coding abnormal circulating..
        hsapiens_homolog_associated_gene_name
                                  <character>
Asl                                       ASL
Apod                                     APOD
Cyp2d22                                CYP2D6
Klk6                                     KLK6
Fcrls                                   FCRL2
Slc2a4                                 SLC2A4
R
dim(rowData(se))
输出
[1] 1474 9对 SummarizedExperiment 进行子集操作
SummarizedExperiment 可以像数据框一样,使用数值、字符或逻辑向量进行子集提取。
下面,我们创建一个 SummarizedExperiment 类的新实例,其中仅包含前 3 个样本的前 5 个特征。
R
se1 <- se[1:5, 1:3]
se1
输出
class: SummarizedExperiment
dim: 5 3
metadata(0):
assays(1): counts
rownames(5): Asl Apod Cyp2d22 Klk6 Fcrls
rowData names(9): gene ENTREZID ... phenotype_description
  hsapiens_homolog_associated_gene_name
colnames(3): GSM2545336 GSM2545337 GSM2545338
colData names(9): sample organism ... tissue mouse
R
colData(se1)
输出
DataFrame with 3 rows and 9 columns
                sample     organism       age         sex   infection
           <character>  <character> <integer> <character> <character>
GSM2545336  GSM2545336 Mus musculus         8      Female  InfluenzaA
GSM2545337  GSM2545337 Mus musculus         8      Female NonInfected
GSM2545338  GSM2545338 Mus musculus         8      Female NonInfected
                strain      time      tissue     mouse
           <character> <integer> <character> <integer>
GSM2545336     C57BL/6         8  Cerebellum        14
GSM2545337     C57BL/6         0  Cerebellum         9
GSM2545338     C57BL/6         0  Cerebellum        10
R
rowData(se1)
输出
DataFrame with 5 rows and 9 columns
               gene  ENTREZID                product    ensembl_gene_id
        <character> <integer>            <character>        <character>
Asl             Asl    109900 argininosuccinate ly.. ENSMUSG00000025533
Apod           Apod     11815 apolipoprotein D, tr.. ENSMUSG00000022548
Cyp2d22     Cyp2d22     56448 cytochrome P450, fam.. ENSMUSG00000061740
Klk6           Klk6     19144 kallikrein related-p.. ENSMUSG00000050063
Fcrls         Fcrls     80891 Fc receptor-like S, .. ENSMUSG00000015852
        external_synonym chromosome_name   gene_biotype  phenotype_description
             <character>     <character>    <character>            <character>
Asl        2510006M18Rik               5 protein_coding abnormal circulating..
Apod                  NA              16 protein_coding abnormal lipid homeo..
Cyp2d22             2D22              15 protein_coding abnormal skin morpho..
Klk6                Bssp               7 protein_coding abnormal cytokine le..
Fcrls      2810439C17Rik               3 protein_coding decreased CD8-positi..
        hsapiens_homolog_associated_gene_name
                                  <character>
Asl                                       ASL
Apod                                     APOD
Cyp2d22                                CYP2D6
Klk6                                     KLK6
Fcrls                                   FCRL2
我们还可以使用 colData()
函数根据样本元数据进行筛选,或使用 rowData()
函数根据特征元数据进行筛选。例如,这里我们仅保留 miRNA
和未感染样本:
R
se1 <- se[rowData(se)$gene_biotype == "miRNA",
          colData(se)$infection == "NonInfected"]
se1
输出
class: SummarizedExperiment
dim: 7 7
metadata(0):
assays(1): counts
rownames(7): Mir1901 Mir378a ... Mir128-1 Mir7682
rowData names(9): gene ENTREZID ... phenotype_description
  hsapiens_homolog_associated_gene_name
colnames(7): GSM2545337 GSM2545338 ... GSM2545353 GSM2545354
colData names(9): sample organism ... tissue mouse
R
assay(se1)
输出
         GSM2545337 GSM2545338 GSM2545343 GSM2545348 GSM2545349 GSM2545353
Mir1901          45         44         74         55         68         33
Mir378a          11          7          9          4         12          4
Mir133b           4          6          5          4          6          7
Mir30c-2         10          6         16         12          8         17
Mir149            1          2          0          0          0          0
Mir128-1          4          1          2          2          1          2
Mir7682           2          0          4          1          3          5
         GSM2545354
Mir1901          60
Mir378a           8
Mir133b           3
Mir30c-2         15
Mir149            2
Mir128-1          1
Mir7682           5
R
colData(se1)
输出
DataFrame with 7 rows and 9 columns
                sample     organism       age         sex   infection
           <character>  <character> <integer> <character> <character>
GSM2545337  GSM2545337 Mus musculus         8      Female NonInfected
GSM2545338  GSM2545338 Mus musculus         8      Female NonInfected
GSM2545343  GSM2545343 Mus musculus         8        Male NonInfected
GSM2545348  GSM2545348 Mus musculus         8      Female NonInfected
GSM2545349  GSM2545349 Mus musculus         8        Male NonInfected
GSM2545353  GSM2545353 Mus musculus         8      Female NonInfected
GSM2545354  GSM2545354 Mus musculus         8        Male NonInfected
                strain      time      tissue     mouse
           <character> <integer> <character> <integer>
GSM2545337     C57BL/6         0  Cerebellum         9
GSM2545338     C57BL/6         0  Cerebellum        10
GSM2545343     C57BL/6         0  Cerebellum        11
GSM2545348     C57BL/6         0  Cerebellum         8
GSM2545349     C57BL/6         0  Cerebellum         7
GSM2545353     C57BL/6         0  Cerebellum         4
GSM2545354     C57BL/6         0  Cerebellum         2
R
rowData(se1)
输出
DataFrame with 7 rows and 9 columns
                gene  ENTREZID        product    ensembl_gene_id
         <character> <integer>    <character>        <character>
Mir1901      Mir1901 100316686  microRNA 1901 ENSMUSG00000084565
Mir378a      Mir378a    723889  microRNA 378a ENSMUSG00000105200
Mir133b      Mir133b    723817  microRNA 133b ENSMUSG00000065480
Mir30c-2    Mir30c-2    723964 microRNA 30c-2 ENSMUSG00000065567
Mir149        Mir149    387167   microRNA 149 ENSMUSG00000065470
Mir128-1    Mir128-1    387147 microRNA 128-1 ENSMUSG00000065520
Mir7682      Mir7682 102466847  microRNA 7682 ENSMUSG00000106406
         external_synonym chromosome_name gene_biotype  phenotype_description
              <character>     <character>  <character>            <character>
Mir1901          Mirn1901              18        miRNA                     NA
Mir378a           Mirn378              18        miRNA abnormal mitochondri..
Mir133b          mir 133b               1        miRNA no abnormal phenotyp..
Mir30c-2        mir 30c-2               1        miRNA                     NA
Mir149            Mirn149               1        miRNA increased circulatin..
Mir128-1          Mirn128               1        miRNA no abnormal phenotyp..
Mir7682      mmu-mir-7682               1        miRNA                     NA
         hsapiens_homolog_associated_gene_name
                                   <character>
Mir1901                                     NA
Mir378a                                MIR378A
Mir133b                                MIR133B
Mir30c-2                               MIR30C2
Mir149                                      NA
Mir128-1                              MIR128-1
Mir7682 NA挑战
提取时间点 0 和时间点 8 中前3个基因的基因表达水平。
R
assay(se)[1:3, colData(se)$time != 4]
输出
        GSM2545336 GSM2545337 GSM2545338 GSM2545341 GSM2545342 GSM2545343
Asl           1170        361        400        988        836        535
Apod         36194      10347       9173      29594      24959      13668
Cyp2d22       4060       1616       1603       3349       3122       2008
        GSM2545346 GSM2545347 GSM2545348 GSM2545349 GSM2545351 GSM2545353
Asl            938       1035        494        481        937        541
Apod         27769      34301      11258      11812      29242      13682
Cyp2d22       2985       3452       1883       2014       3678       2216
        GSM2545354 GSM2545380
Asl            473       1192
Apod         11088      38148
Cyp2d22       1821       4019
R
# Equivalent to
assay(se)[1:3, colData(se)$time == 0 | colData(se)$time == 8]
输出
        GSM2545336 GSM2545337 GSM2545338 GSM2545341 GSM2545342 GSM2545343
Asl           1170        361        400        988        836        535
Apod         36194      10347       9173      29594      24959      13668
Cyp2d22       4060       1616       1603       3349       3122       2008
        GSM2545346 GSM2545347 GSM2545348 GSM2545349 GSM2545351 GSM2545353
Asl            938       1035        494        481        937        541
Apod         27769      34301      11258      11812      29242      13682
Cyp2d22       2985       3452       1883       2014       3678       2216
        GSM2545354 GSM2545380
Asl            473       1192
Apod         11088      38148
Cyp2d22 1821 4019挑战
验证使用长格式 rna 表格是否能得到相同的值。
R
rna |>
    filter(gene %in% c("Asl", "Apod", "Cyd2d22")) |>
    filter(time != 4) |>
    select(expression)
输出
# A tibble: 28 × 1
   expression
        <dbl>
 1       1170
 2      36194
 3        361
 4      10347
 5        400
 6       9173
 7        988
 8      29594
 9        836
10      24959
# ℹ 18 more rows
长表和 SummarizedExperiment
包含相同的信息,但结构有所不同。两种方法各有优势:前者适用于
tidyverse
包,而后者则是许多生物信息学和统计处理步骤的首选结构。例如,使用
DESeq2 包进行的典型 RNA-Seq 分析。
向元数据添加变量
我们还可以向元数据中添加信息。假设你想添加样本采集中心的信息……
R
colData(se)$center <- rep("University of Illinois", nrow(colData(se)))
colData(se)
输出
DataFrame with 22 rows and 10 columns
                sample     organism       age         sex   infection
           <character>  <character> <integer> <character> <character>
GSM2545336  GSM2545336 Mus musculus         8      Female  InfluenzaA
GSM2545337  GSM2545337 Mus musculus         8      Female NonInfected
GSM2545338  GSM2545338 Mus musculus         8      Female NonInfected
GSM2545339  GSM2545339 Mus musculus         8      Female  InfluenzaA
GSM2545340  GSM2545340 Mus musculus         8        Male  InfluenzaA
...                ...          ...       ...         ...         ...
GSM2545353  GSM2545353 Mus musculus         8      Female NonInfected
GSM2545354  GSM2545354 Mus musculus         8        Male NonInfected
GSM2545362  GSM2545362 Mus musculus         8      Female  InfluenzaA
GSM2545363  GSM2545363 Mus musculus         8        Male  InfluenzaA
GSM2545380  GSM2545380 Mus musculus         8      Female  InfluenzaA
                strain      time      tissue     mouse                 center
           <character> <integer> <character> <integer>            <character>
GSM2545336     C57BL/6         8  Cerebellum        14 University of Illinois
GSM2545337     C57BL/6         0  Cerebellum         9 University of Illinois
GSM2545338     C57BL/6         0  Cerebellum        10 University of Illinois
GSM2545339     C57BL/6         4  Cerebellum        15 University of Illinois
GSM2545340     C57BL/6         4  Cerebellum        18 University of Illinois
...                ...       ...         ...       ...                    ...
GSM2545353     C57BL/6         0  Cerebellum         4 University of Illinois
GSM2545354     C57BL/6         0  Cerebellum         2 University of Illinois
GSM2545362     C57BL/6         4  Cerebellum        20 University of Illinois
GSM2545363     C57BL/6         4  Cerebellum        12 University of Illinois
GSM2545380     C57BL/6         8  Cerebellum        19 University of Illinois
这说明了元数据槽可以无限扩展,而不会影响其他结构!
tidySummarizedExperiment
您可能会好奇,是否可以使用 tidyverse 命令来操作
SummarizedExperiment 对象?答案是肯定的,我们可以使用
tidySummarizedExperiment 包来实现。
请回顾一下我们的 SummarizedExperiment 对象是什么样子的:
R
se
输出
class: SummarizedExperiment
dim: 1474 22
metadata(0):
assays(1): counts
rownames(1474): Asl Apod ... Lmx1a Pbx1
rowData names(9): gene ENTREZID ... phenotype_description
  hsapiens_homolog_associated_gene_name
colnames(22): GSM2545336 GSM2545337 ... GSM2545363 GSM2545380
colData names(10): sample organism ... mouse center
加载 tidySummarizedExperiment,然后再次查看 se
对象。
R
## BiocManager::install("tidySummarizedExperiment")
library("tidySummarizedExperiment")

se
输出
class: SummarizedExperiment
dim: 1474 22
metadata(0):
assays(1): counts
rownames(1474): Asl Apod ... Lmx1a Pbx1
rowData names(9): gene ENTREZID ... phenotype_description
  hsapiens_homolog_associated_gene_name
colnames(22): GSM2545336 GSM2545337 ... GSM2545363 GSM2545380
colData names(10): sample organism ... mouse center
它仍然是一个 SummarizedExperiment
对象,因此保留了高效的结构,但现在我们可以将其视为一个
tibble。请注意,输出的第一行指出这是一个
SummarizedExperiment-tibble
抽象。我们还可以在输出的第二行看到转录本和样本的数量。
现在我们可以使用 tidyverse 命令来操作
SummarizedExperiment 对象了。
我们可以使用 filter
根据条件筛选行,例如查看某个样本的所有行。
R
se |> filter(sample == "GSM2545336")
输出
class: SummarizedExperiment
dim: 1474 1
metadata(1): latest_filter_scope_report
assays(1): counts
rownames(1474): Asl Apod ... Lmx1a Pbx1
rowData names(9): gene ENTREZID ... phenotype_description
  hsapiens_homolog_associated_gene_name
colnames(1): GSM2545336
colData names(10): sample organism ... mouse center
R
se |> filter(sex == "Female")
输出
class: SummarizedExperiment
dim: 1474 12
metadata(1): latest_filter_scope_report
assays(1): counts
rownames(1474): Asl Apod ... Lmx1a Pbx1
rowData names(9): gene ENTREZID ... phenotype_description
  hsapiens_homolog_associated_gene_name
colnames(12): GSM2545336 GSM2545337 ... GSM2545362 GSM2545380
colData names(10): sample organism ... mouse center
我们可以使用 select 来指定想要查看的列。
R
se |> select(sample, sex)
警告
Warning: `when()` was deprecated in purrr 1.0.0.
ℹ Please use `if` instead.
ℹ The deprecated feature was likely used in the tidySummarizedExperiment
  package.
  Please report the issue at
  <https://github.com/stemangiola/tidySummarizedExperiment/issues>.
This warning is displayed once per session.
Call `lifecycle::last_lifecycle_warnings()` to see where this warning was
generated.
输出
tidySummarizedExperiment says: Key columns are missing. A data frame is returned for independent data analysis.输出
# A tibble: 32,428 × 2
   sample     sex
   <chr>      <chr>
 1 GSM2545336 Female
 2 GSM2545336 Female
 3 GSM2545336 Female
 4 GSM2545336 Female
 5 GSM2545336 Female
 6 GSM2545336 Female
 7 GSM2545336 Female
 8 GSM2545336 Female
 9 GSM2545336 Female
10 GSM2545336 Female
# ℹ 32,418 more rows
我们可以使用 mutate 来添加元数据信息。
R
se |> mutate(center = "Heidelberg University")
输出
class: SummarizedExperiment
dim: 1474 22
metadata(1): latest_mutate_scope_report
assays(1): counts
rownames(1474): Asl Apod ... Lmx1a Pbx1
rowData names(9): gene ENTREZID ... phenotype_description
  hsapiens_homolog_associated_gene_name
colnames(22): GSM2545336 GSM2545337 ... GSM2545363 GSM2545380
colData names(10): sample organism ... mouse center
我们还可以使用 tidyverse 管道 |>
来组合命令。例如,我们可以将 group_by 和
summarise 组合起来,以获取每个样本的总计数。
R
se |>
    group_by(.sample) |>
    summarise(total_counts=sum(counts))
输出
tidySummarizedExperiment says: A data frame is returned for independent data analysis.输出
# A tibble: 22 × 2
   .sample    total_counts
   <chr>             <int>
 1 GSM2545336      3039671
 2 GSM2545337      2602360
 3 GSM2545338      2458618
 4 GSM2545339      2500082
 5 GSM2545340      2479024
 6 GSM2545341      2413723
 7 GSM2545342      2349728
 8 GSM2545343      3105652
 9 GSM2545344      2524137
10 GSM2545345      2506038
# ℹ 12 more rows
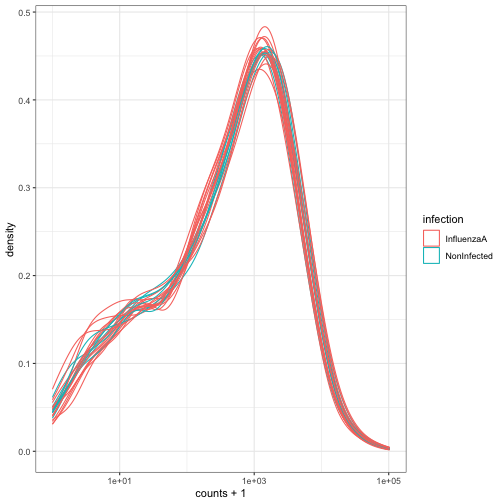
我们可以将 tidy SummarizedExperiment 对象视为一个普通的 tibble 进行绘图。
这里我们绘制每个样本的计数分布。
R
se |>
    ggplot(aes(counts + 1, group=.sample, color=infection)) +
    geom_density() +
    scale_x_log10() +
    theme_bw()
有关 tidySummarizedExperiment 的更多信息,请参阅 包网站。
核心要点
SummarizedExperiment是一种高效的组学数据存储与处理方式。它们被广泛应用于许多 Bioconductor 包中。
如果您参加接下来的专注于 RNA 测序分析的培训,您将学习如何使用
Bioconductor DESeq2
包进行一些差异表达分析。DESeq2 包的整个分析过程都在
SummarizedExperiment 中处理。
- Bioconductor 是一个为理解高通量生物学数据提供支持和软件包的项目。
-
SummarizedExperiment是一种用于存储和管理高通量组学数据的对象类型。
Bioconductor 由 R 语言的两位创始人之一 Robert Gentleman 发起。Bioconductor 提供专门用于组学数据分析的工具。Bioconductor 使用 R 统计编程语言,且采用开源和开放开发模式。↩︎